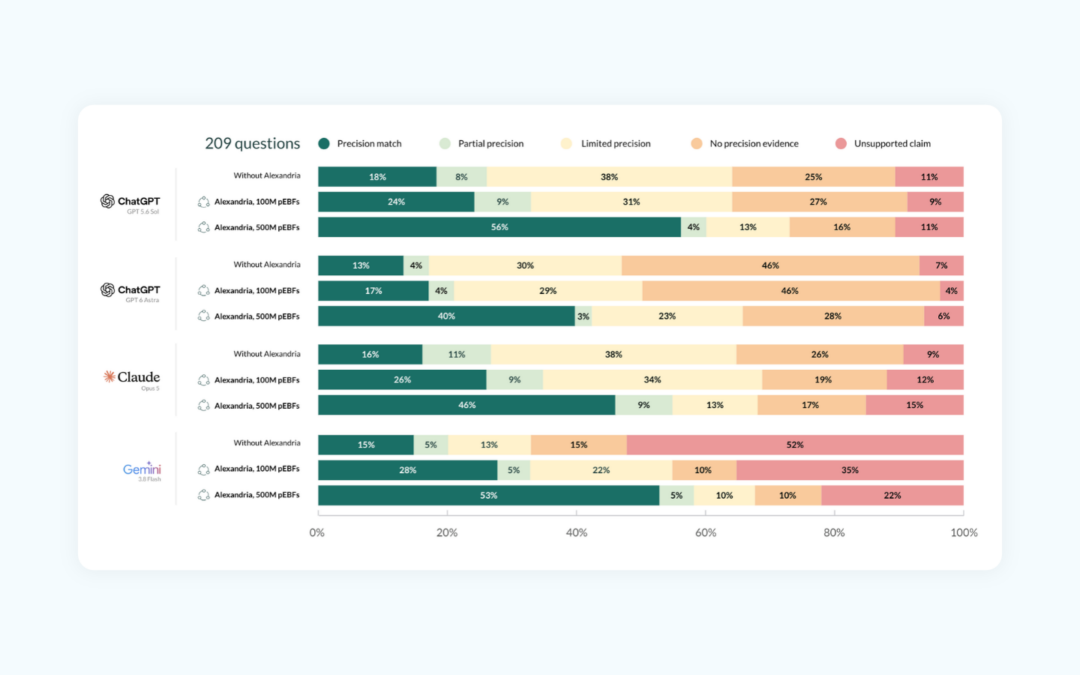
Precision Evidence Bench is a first-of-its-kind benchmark that transforms how the healthcare ecosystem evaluates clinical AI. Unlike traditional medical AI benchmarks, it tests model performance against real-world clinical queries grounded in complex patient history. Findings demonstrate that clinical large language models (LLMs) struggle without direct patient context, but their accuracy improves by over 300% when equipped with high-quality real-world evidence. The benchmark proves that LLM performance scales directly with evidence availability.
Clinical LLM Performance Improves by >300% When Provided With High-Quality Real-World Evidence in New Precision Medicine Benchmark